An Expert Report on Amazon S3 Vectors: Technology, Economics, and Market Impact
Executive Summary
On July 15, 2025, Amazon Web Services (AWS) announced the preview of Amazon S3 Vectors, a service that integrates native vector storage and search capabilities directly into its flagship object storage service, Amazon S3. This development represents a pivotal moment for the Artificial Intelligence (AI) and data management industries. Positioned not as a direct replacement for high-performance vector databases but as a new, cost-optimized storage tier, S3 Vectors is poised to fundamentally reshape the economics and architecture of AI applications, particularly those leveraging Retrieval-Augmented Generation (RAG).
The core value proposition of S3 Vectors is a dramatic reduction in the total cost of ownership for vector data—claimed to be up to 90%—by shifting the pricing model from always-on compute instances to a pay-as-you-go model based on storage and query volume. Architecturally, the service introduces “Vector Buckets” and “Vector Indexes” built upon S3’s renowned infrastructure for durability and scale, offering sub-second query performance suitable for a large class of non-real-time workloads, such as batch analytics and archival RAG.
This report provides an exhaustive analysis of Amazon S3 Vectors, covering its technology, economic model, and strategic implications. Key findings include:
- A Strategic Commoditization of Storage: S3 Vectors is not a “vector database killer.” Rather, it is a strategic move to commoditize the “warm” and “cold” tiers of vector storage. By offering a “good enough” performance profile at a fraction of the cost, AWS is creating a new market category that will capture a significant volume of vector data currently deemed too expensive to store in specialized databases.
- Market Bifurcation and Vendor Response: The introduction of S3 Vectors will force a bifurcation of the market into a low-cost, high-volume “utility” tier and a high-performance, low-latency “premium” tier. Standalone vector database vendors like Pinecone, Weaviate, and Qdrant are now compelled to differentiate on extreme performance, advanced hybrid search features, and multi-cloud or on-premise deployment models to justify their higher cost structure.
- The Rise of Tiered Vector Architectures: The most significant architectural implication is the formalization of a tiered vector storage strategy as a best practice. Enterprises will be incentivized to design applications that use high-performance databases for “hot,” real-time data while leveraging S3 Vectors for less latency-sensitive “warm” and “cold” data, managed through a sophisticated application-level query orchestration layer.
- A New Front in the Cloud Wars: S3 Vectors is the latest move in the broader competition among hyperscalers. While AWS focuses on bottom-up cost disruption, Google Cloud Platform (GCP) leads with a performance-first strategy via Vertex AI Search, and Microsoft Azure emphasizes enterprise flexibility with a wide array of vector-enabled database services. The choice of platform will increasingly depend on an organization’s existing cloud ecosystem and strategic priorities.
For technology leaders, the advent of Amazon S3 Vectors necessitates a re-evaluation of AI data strategies. It presents a powerful tool for cost optimization but requires a nuanced understanding of its performance trade-offs and a willingness to adopt more sophisticated, tiered application architectures. This report serves as a comprehensive guide for navigating this new landscape.
I. The Advent of Integrated Vector Storage: Unpacking the Amazon S3 Vectors Announcement
The July 15, 2025, Announcement: A New Paradigm for AI Data
On July 15, 2025, Amazon Web Services (AWS) formally introduced Amazon S3 Vectors, making it available in a public preview.1 The announcement marked a significant strategic expansion for what is arguably AWS’s most foundational service, Amazon S3. The core messaging was precise and impactful: S3 Vectors is the “first cloud object storage with native support for storing and querying vectors”.2 This framing is a deliberate and crucial element of its market positioning. Instead of launching a new, standalone database product, AWS has chosen to extend the capabilities of S3, a service synonymous with near-infinite scalability, eleven nines of durability, and unparalleled cost-effectiveness. This approach allows AWS to leverage decades of customer trust and familiarity with S3 to introduce a new, disruptive capability for the burgeoning AI market.
Core Value Proposition: Commoditizing Vector Storage at Scale
The central pillar of the S3 Vectors announcement is a dramatic economic promise: the ability to reduce the total cost of uploading, storing, and querying vector embeddings by “up to 90 percent” compared to alternative solutions.1 This striking figure is the primary lever designed to capture the attention of enterprises struggling with the high costs associated with scaling generative AI applications.
Critically, the service is explicitly “purpose-built” for the durable, long-term storage of large vector datasets.3 Its performance profile is defined as “subsecond query performance,” a metric that is intentionally positioned as sufficient for many use cases but distinct from the millisecond-level latency offered by high-performance, in-memory vector databases.1 AWS acknowledges that S3 Vectors is ideal for “infrequent query workloads” and that customers should be prepared for a “performance tradeoff” in exchange for the significant cost benefits.1 This careful positioning manages expectations and clearly defines the target market: large-scale RAG, semantic search over historical archives, and AI agent memory, where cost and scalability are more critical than real-time interactive speed.
Initial Availability and Preview Status Limitations
As is standard for new AWS services, S3 Vectors was launched in preview across a select number of regions: US East (N. Virginia), US East (Ohio), US West (Oregon), Europe (Frankfurt), and Asia Pacific (Sydney).3 This initial footprint requires organizations planning global deployments to consider data residency and latency implications.
The “preview” designation also carries important caveats for early adopters. The feature set and performance characteristics are subject to change before general availability. More importantly, early user reports have highlighted significant operational limitations. For instance, a key constraint noted is that deleting individual vectors currently necessitates a full recreation of the vector index.6 Furthermore, index updates are handled asynchronously with eventual consistency, meaning there is a potential delay between when data is written and when it becomes queryable.6 These limitations reinforce the service’s suitability for more static, archival, or batch-oriented workloads rather than dynamic, transactional systems.
Strategic Positioning within the AWS AI and Data Stack
A defining characteristic of the S3 Vectors launch is its immediate and deep integration into the existing AWS AI and data ecosystem. It is not an isolated service but a connective tissue designed to enhance and reduce the cost of other key AWS products.
- Amazon Bedrock Knowledge Bases: This is the flagship integration. Customers building RAG applications can now select S3 Vectors as a native, low-cost vector store directly within the Bedrock console.1 This addresses one of the primary cost drivers and operational complexities of deploying RAG at scale: the provisioning and management of a separate vector database cluster.1
- Amazon OpenSearch Service: S3 Vectors is explicitly positioned to work in tandem with OpenSearch in a tiered storage architecture. The strategy encourages users to store infrequently accessed or “warm” vectors cost-effectively in S3 Vectors, while “hot” data requiring real-time, low-latency query performance can be exported to an OpenSearch cluster.3 This provides a clear, AWS-native path for balancing cost and performance.
- Amazon SageMaker Unified Studio: To streamline the machine learning operations (MLOps) lifecycle, S3 Vectors is also integrated as a vector store option within SageMaker Unified Studio. This allows data scientists and ML engineers to build and test generative AI applications that leverage S3 Vectors without leaving their primary development environment.3
This immediate, multi-faceted integration signals AWS’s intent for S3 Vectors to become a foundational component of its AI stack. The strategy is not merely to offer a new tool but to create a powerful “gravity well” that makes the entire AWS ecosystem more cost-effective and functionally cohesive for building AI applications.
II. Architectural Deep Dive: The Inner Workings of Amazon S3 Vectors
To fully grasp the strategic implications of Amazon S3 Vectors, it is essential to understand its underlying architecture. The service introduces new S3 primitives and a managed, storage-first design that prioritizes cost and scalability over the raw performance of compute-centric databases.
The S3 Vector Bucket: A New Storage Primitive
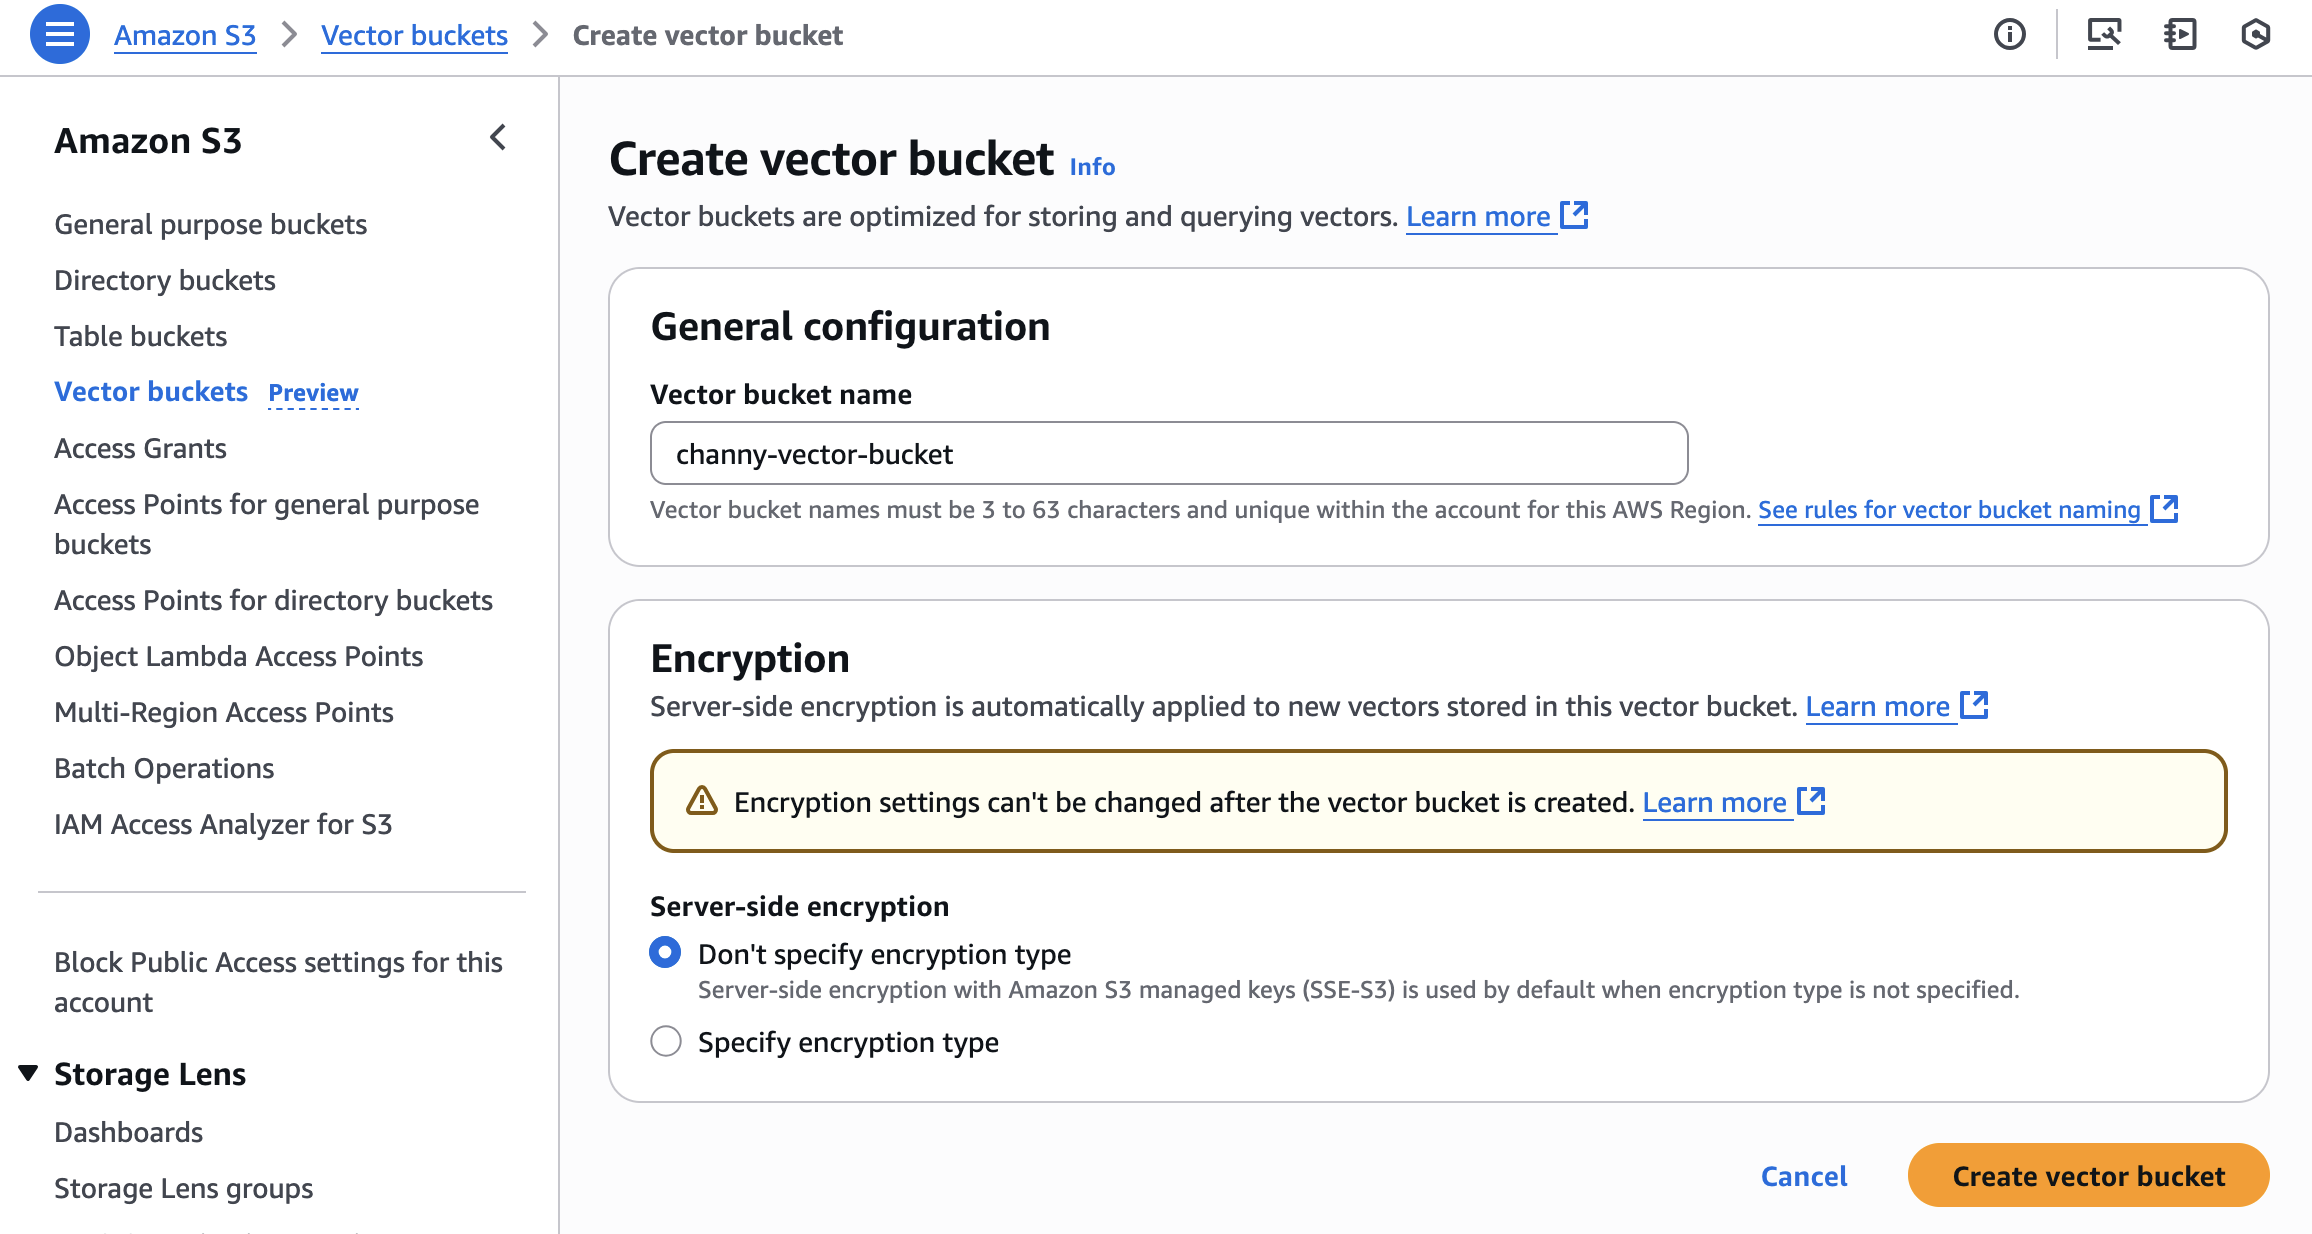
The foundation of the service is the “Vector bucket,” a new and distinct bucket type within the S3 ecosystem.3 Unlike standard S3 buckets, vector buckets are equipped with a dedicated set of APIs designed specifically for storing, indexing, and querying vector data.3 This architectural separation allows AWS to optimize the underlying infrastructure for vector workloads without altering the behavior of its general-purpose object storage.
The creation and naming of these buckets adhere to strict conventions. Names must be between 3 and 63 characters, use only lowercase letters, numbers, and hyphens, and must be unique within a given AWS region and account.8 Each vector bucket is assigned a unique Amazon Resource Name (ARN) with a specific format,
arn:aws:s3-vectors:<Region>:<AccountID>:bucket/<bucket-name>, which is used for integration with other AWS services like IAM.8
Vector Indexing: Structure, Scalability, and Configuration
Within each vector bucket, data is organized into “vector indexes”.3 This two-level hierarchy (bucket -> index) provides a flexible structure for managing diverse datasets. A single vector bucket can support up to 10,000 indexes, with each index capable of holding tens of millions of vectors.3 This allows for logical partitioning of data, for example, by tenant in a multi-tenant application or by data source in a large-scale RAG system.
The core of the service’s search capability lies in its indexing mechanism. While AWS has not publicly disclosed the specific Approximate Nearest Neighbor (ANN) algorithm used, expert analysis suggests it is likely a proven, industry-standard method such as Hierarchical Navigable Small World (HNSW) or Inverted File with Product Quantization (IVF-PQ), adapted to operate on S3’s massively parallel, distributed storage plane.7 AWS describes the process as being fully managed, stating that S3 Vectors “automatically optimizes the vector data to achieve the best possible price-performance” as the dataset evolves.3 This opaque, serverless approach abstracts the complexity of index tuning and maintenance from the user.
When creating an index, users must define several key parameters:
- Dimensions: A fixed integer between 1 and 4096 that specifies the length of the vectors to be stored. All vectors within a single index must have the same dimensionality to ensure compatibility.8
- Distance Metric: The algorithm used to measure similarity. S3 Vectors supports Cosine similarity, which is ideal for semantic search where the direction of vectors is most important, and Euclidean (L2) distance, which considers both magnitude and direction.3 The choice should be aligned with the output of the embedding model used to generate the vectors.
- Metadata Filtering: A critical feature for enabling hybrid search. Each vector can have key-value metadata attached, allowing queries to be filtered based on structured attributes before the similarity search is performed.1 However, there is a crucial limitation: while a vector can have up to 40 KB of total metadata, only 2 KB of that can be designated as
filterable.1 This filterable metadata can consist of string, number, or boolean types and is used to narrow the search space, for example, to find similar documents
where author = ‘John Doe’ and year > 2023. This constraint means that while S3 Vectors supports hybrid search, it is less suited for applications that rely on complex filtering across large metadata payloads.
API and Data Operations: Insert, Query, List, and Delete
Interaction with S3 Vectors is handled through a new, dedicated set of APIs, which are accessible via the AWS Command Line Interface (CLI), AWS SDKs, and the S3 REST API.3 The API includes operations such as
InsertVectors, QueryVectors, and ListVectors.9
The service’s architecture, optimized for storage over real-time transactions, is reflected in its operational characteristics:
- Consistency Model: Index updates follow an eventual consistency model.6 This means there can be a propagation delay, estimated to be from seconds to minutes, before newly inserted or updated vectors are reflected in query results.7 This makes the service unsuitable for applications requiring read-after-write consistency.
- Deletions: A significant operational hurdle in the preview version is the handling of deletions. Currently, removing vectors requires a full recreation of the index.6 This is a costly and slow operation, rendering S3 Vectors impractical for workloads with high churn or frequent data updates.
Security and Compliance: Encryption, IAM, and Audit Trail Considerations
S3 Vectors inherits the robust security posture of the broader S3 service.
- Encryption: Data is encrypted by default using server-side encryption with S3-managed keys (SSE-S3). For more stringent security requirements, customers can opt to use server-side encryption with AWS Key Management Service (SSE-KMS) keys, providing customer-managed control over the encryption keys.1
- Access Control: Access to vector buckets and indexes is governed by standard AWS Identity and Access Management (IAM) policies. This allows for fine-grained control over which users or roles can perform actions like creating indexes, inserting vectors, or executing queries.1
- Audit Trails: It is expected that API-level calls to the S3 Vectors service will be logged in AWS CloudTrail, providing an audit trail of management actions. However, it remains unconfirmed whether the content of the similarity search queries themselves will be logged.7 This ambiguity is a critical consideration for organizations in regulated industries like healthcare or finance that require deep auditability of data access.
Performance Profile: Sub-Second Latency and Throughput Expectations
AWS officially markets S3 Vectors with “subsecond query performance”.1 This intentionally broad term sets it apart from high-performance databases that promise single or double-digit millisecond latency. Independent analysis and expert inference provide a more granular expectation:
- Latency: For moderately sized indexes (1-10 million vectors), P50 (median) query latencies are expected to be in the 100-500ms range. However, P95 (95th percentile) latencies could exceed 1 second, particularly under high concurrent load or when complex metadata filters are applied.7 This performance profile is sufficient for many asynchronous or batch RAG tasks but is too slow for real-time, interactive applications like e-commerce search or live recommendation engines.
- Throughput: Query throughput is likely governed by the standard S3 request rate limits, which allow for thousands of requests per second per prefix.7 While this is a high ceiling, it is a different scaling model from dedicated database clusters that can be provisioned for extremely high queries per second (QPS).
The entire architectural design of S3 Vectors points to a “storage-first, compute-second” philosophy. Unlike traditional databases that are optimized to keep indexes in hot memory to minimize query latency, S3 Vectors is designed to minimize the cost of storing petabytes of data at rest. This is evident in its reliance on S3’s storage plane, its serverless query model that avoids paying for idle compute, and its acceptance of trade-offs like eventual consistency and slow deletions. This architecture is what enables the dramatic cost savings and the natural, tiered integration with a “compute-first” service like Amazon OpenSearch.
The following table provides a consolidated summary of the key technical specifications for Amazon S3 Vectors.
Table 1: Amazon S3 Vectors – Technical Specifications
| Feature | Specification | Source Snippet(s) |
| Bucket & Index Limits | Up to 10,000 vector indexes per vector bucket. | 3 |
| Each vector index can hold tens of millions of vectors. | 3 | |
| Vector Dimensions | Must be a fixed integer between 1 and 4096. | 8 |
| Distance Metrics | Cosine or Euclidean. | 3 |
| Metadata Limits | Up to 40 KB of total metadata per vector. | 1 |
| Up to 2 KB of filterable metadata per vector. | 1 | |
| API Endpoints | Dedicated set of APIs for vector operations (e.g., InsertVectors, QueryVectors). | 3 |
| Consistency Model | Eventual consistency for index updates. | 6 |
| Encryption | Server-Side Encryption with S3-Managed Keys (SSE-S3) by default. | 1 |
| Option for Server-Side Encryption with AWS KMS Keys (SSE-KMS). | 1 | |
| Preview Regions | US East (N. Virginia), US East (Ohio), US West (Oregon), Europe (Frankfurt), Asia Pacific (Sydney). | 4 |
| Deletion Process (Preview) | Requires full index recreation to delete vectors. | 6 |
III. The Economics of Vector Storage: A Comprehensive Analysis of S3 Vectors Pricing and Cost Savings
The primary driver behind the development and adoption of Amazon S3 Vectors is economics. The service’s pricing model is a radical departure from the instance-based pricing of traditional vector databases and is engineered to deliver on the headline claim of up to 90% cost savings for specific, yet common, workloads.
Deconstructing the Pricing Model: Storage, PUT, and Query Costs
The S3 Vectors pricing model is unbundled into three core components, reflecting a serverless, pay-as-you-go philosophy.11 This structure directly attacks the primary cost center of many existing vector database solutions: idle, provisioned compute.
- Storage Cost: This is a recurring monthly fee based on the logical size of the data stored in vector indexes. The rate provided in examples is $0.06 per GB per month.6 While this is roughly three times the cost of S3 Standard storage (~$0.023/GB/month 11), it is substantially cheaper than the cost of the high-performance EBS storage typically attached to database instances. The logical size includes the vector data itself (where each dimension is 4 bytes), all associated metadata (both filterable and non-filterable), and the vector key.11
- PUT (Ingestion) Cost: This is a one-time charge for uploading data into a vector index, priced per gigabyte of data ingested. An example rate is $0.20 per GB.11 This cost is incurred whenever new vectors are added or an index is rebuilt.
- Query Cost: This is the most complex component and consists of two parts: a small fee per API request (e.g., $2.50 per million queries) and a usage-based charge for the data processed during the query.11 The amount of data processed is calculated based on the number of vectors in the index multiplied by the average size of each vector. Crucially, this calculation only includes the vector data, the key, and the
filterable metadata.11 Non-filterable metadata can be returned in query results at no extra data processing cost. The pricing for data processed is tiered, becoming cheaper per terabyte as the index size grows, incentivizing large-scale use.11
This pricing model fundamentally changes the cost equation. It directly ties expenditure to usage, making it highly attractive for applications with variable or infrequent query patterns, and it creates a direct financial incentive for developers to be efficient with their data architecture.
Scenario Modeling: Cost Analysis for Different Workloads
To understand the real-world impact of this pricing model, it is useful to analyze two distinct workload scenarios.
- Scenario 1: Storage-Heavy, Query-Light (Archival RAG or Development)
This scenario represents a common use case where a large corpus of documents is indexed for occasional semantic search. An example workload involves storing 10 million vectors with a relatively low query volume of 250,000 queries per month.
- Traditional Vector Database: Running this on a dedicated instance (e.g., an r7g.2xlarge) could cost over $300 per month for the compute instance alone, before considering storage, data transfer, and management overhead.12 The cost is incurred even if zero queries are run.
- Amazon S3 Vectors: The same workload is estimated to cost just over $30 per month.9 The cost is dominated by storage, with query costs being minimal. This scenario is where the “up to 90% savings” claim is most tangible and credible.
- Scenario 2: Storage-Heavy, Query-Heavy (Large-Scale Analytics)
This scenario models a more intensive application, such as a large-scale semantic search service, with 400 million vectors and a high volume of 10 million queries per month.
- Amazon S3 Vectors Breakdown 11:
- Storage Cost: ~$141 per month.
- PUT Cost (Amortized): ~$78 per month.
- Query Cost: ~$997 per month.
- Total Estimated Cost: ~$1,217 per month.
In this high-throughput scenario, the query processing charge becomes the dominant cost factor. While this is still likely to be significantly cheaper than provisioning and managing a massive, multi-node cluster of a dedicated vector database capable of handling this load, the savings are far less than 90%.
Validating the “Up to 90% Savings” Claim: A Realistic Assessment
The “up to 90%” figure is a powerful marketing tool, but it is conditional. The analysis confirms that such savings are achievable, but primarily for workloads where the cost of always-on, provisioned compute in a traditional vector database is the largest expense. For applications with low to moderate query volumes, S3 Vectors offers a transformative cost reduction. However, as query volume and frequency increase, the pay-per-query data scanning costs will accumulate, and the total cost savings will diminish. Enterprises must therefore model their specific query patterns and data volumes to arrive at a realistic cost estimate rather than relying on the headline marketing figure.
The Hidden Costs: Integration Overhead and Performance Trade-offs
A purely financial analysis is incomplete without considering the associated “hidden” costs.
- Development and Integration Overhead: The most cost-effective way to use S3 Vectors in a system with mixed latency requirements is within a tiered architecture. However, this requires building a custom application layer for query routing—logic that decides whether to query the “hot” tier (e.g., OpenSearch) or the “warm” tier (S3 Vectors)—and for merging the results. This adds significant development complexity, testing, and maintenance overhead, which must be factored into the total cost of ownership.10
- The Business Cost of Performance: For applications where user experience is tied to low latency, the higher and more variable performance of S3 Vectors (e.g., 200-500ms) compared to a dedicated database (<100ms) can have a direct business impact.10 Slower response times can lead to lower user engagement, reduced conversion rates, or a perception of poor quality, which are non-trivial business costs that do not appear on a cloud bill.
The following table provides a simplified cost comparison to illustrate the economic trade-offs between S3 Vectors and a representative standalone vector database for a low-query workload.
Table 2: Illustrative Cost Comparison – S3 Vectors vs. Representative Standalone Vector DB
(Based on a workload of 10 million vectors and 1 million queries/month)
| Cost Component | Amazon S3 Vectors (Low-Query Scenario) | Representative Standalone DB (e.g., Pinecone Pod) |
| Monthly Compute/Instance Cost | $0 (Serverless) | ~$276 – $1,105 (Based on 1-4 p2.x1 pods) |
| Storage Cost | ~$1.38 (for ~60GB) | Included in pod price, but scales with pods |
| Ingestion/PUT Cost | ~$2.00 (Amortized for one full upload) | Typically included in pod price |
| Query Cost | ~$4.00 (for 1M queries) | Included in pod price |
| Total Estimated Monthly Cost | ~$7.38 | ~$276 – $1,105 |
Note: Figures are illustrative and based on pricing and scenarios described in sources.7 Actual costs will vary based on vector dimensions, metadata size, query patterns, and specific vendor pricing.
IV. The Vector Database Ecosystem: A Primer on Core Concepts and Applications
To fully appreciate the significance of Amazon S3 Vectors and its impact on the market, it is necessary to understand the foundational technology of vector embeddings and the role that vector databases play in the modern AI landscape. This technology is the engine behind the shift from keyword-based retrieval to semantic, meaning-based understanding.
From Unstructured Data to Vector Embeddings: The Foundation of Semantic Understanding
The vast majority of the world’s data is unstructured: text from documents and emails, pixels from images, audio waves from recordings, and frames from videos. Traditional databases, which are designed for neatly organized rows and columns, struggle to handle this type of data. The breakthrough of modern AI, particularly deep learning, was the development of embedding models. These are specialized machine learning models that can take a piece of unstructured data as input and convert it into a numerical representation called a vector embedding.13
A vector embedding is a list of numbers (a vector) in a high-dimensional space. The key property of these embeddings is that they capture the semantic meaning or conceptual essence of the original data. Objects with similar meanings are mapped to points that are close to each other in this vector space.15 For example, an embedding model trained on text would produce vectors for the words “car” and “automobile” that are very close together, while the vector for “planet” would be far away.17 This principle applies to all data types; a model can learn to place images of “golden retrievers” near each other, or audio clips of “jazz music” in a similar region of the vector space.
The Role of Vector Databases in Modern AI
Once data has been converted into vector embeddings, a specialized system is needed to manage them. This is the role of a vector database. A vector database is a database system purpose-built to efficiently store, index, and query vast quantities of high-dimensional vectors.18
Its primary function is fundamentally different from that of a traditional database. Instead of searching for exact matches (e.g., WHERE user_id = 123), a vector database performs similarity search. Given a query vector, the database uses specialized algorithms to find the k vectors in its index that are “closest” or most similar, based on a mathematical distance metric like Cosine Similarity or Euclidean Distance.14 This process is often called
Approximate Nearest Neighbor (ANN) search, as algorithms trade a small amount of perfect accuracy for a massive gain in speed, making it possible to search through billions of vectors in milliseconds or sub-seconds.14
Key Use Cases Explored
The ability to search based on semantic meaning has unlocked a wide range of powerful applications across numerous industries.
- Retrieval-Augmented Generation (RAG): This is arguably the most prominent and impactful use case for vector databases today. To combat the tendency of Large Language Models (LLMs) to “hallucinate” or provide outdated information, RAG architectures use a vector database as an external knowledge source. A company’s internal documents, product manuals, or support tickets are chunked, converted to embeddings, and stored. When a user asks a question, the question is also converted to a vector. A similarity search retrieves the most relevant document chunks from the database. These chunks are then provided to the LLM as context along with the original question, enabling the model to generate a factual, accurate, and up-to-date response grounded in the provided data.13
- Semantic and Multimodal Search: Vector databases power next-generation search engines that understand user intent. This allows users to search for “healthy dinner recipes without nuts” and get conceptually relevant results, even if the exact keywords are not present. This extends to multimodal search, where one type of data can be used to search another, such as using a text query like “a person walking down a runway in a silver dress” to find specific scenes within a massive video archive.5
- Recommendation Engines: E-commerce sites, streaming services, and content platforms use vector databases to provide personalized recommendations. User preferences and item characteristics (e.g., product descriptions, movie genres, song melodies) are represented as vectors. The system can then recommend items whose vectors are closest to a user’s preference vector, or similar to items they have previously liked.18
- Anomaly and Fraud Detection: By creating vector embeddings of normal behavior (e.g., typical transaction patterns), systems can identify anomalies and potential fraud by finding data points whose vectors are significant outliers, far from the cluster of normal activity.18
- Industry-Specific Applications: The technology is being applied in specialized fields:
- Healthcare & Life Sciences: Finding patients with similar medical histories, analyzing medical images for diagnostic patterns, and accelerating drug discovery by searching for molecular structures with similar vector representations.18
- Autonomous Vehicles: Real-time processing of sensor data from LiDAR and cameras. Environmental features are converted to vectors to enable rapid obstacle detection and navigation decisions.18
- Media & Entertainment: Managing petabyte-scale media archives and enabling content discovery through semantic search.5
In essence, vector databases provide the critical infrastructure that allows AI models to connect with and reason about the world’s vast stores of unstructured data, moving beyond simple data retrieval to genuine information discovery.
V. Market Disruption Analysis: The Impact of S3 Vectors on the Standalone Vector Database Market
The launch of Amazon S3 Vectors is more than a new product release; it is a strategic maneuver that sends a powerful shockwave through the burgeoning vector database market. By integrating vector search as a native feature into its most ubiquitous storage service, AWS is fundamentally altering the competitive landscape, threatening the business models of specialized startups and forcing a re-evaluation of what it means to be a “vector database.”
The Commoditization Threat: AWS vs. the Specialists
The central disruptive force of S3 Vectors is commoditization. AWS is effectively unbundling the core functions of a vector database and offering the most expensive part—scalable, durable storage—at a dramatically lower cost. This move follows a classic pattern where a dominant platform provider absorbs a niche feature, transforming it from a standalone product category into an integrated capability of the broader platform.24 This has been seen before with technologies like full-text search and JSON document storage, which were once the domain of specialized databases but are now standard features in mainstream relational and NoSQL systems like PostgreSQL and MongoDB.
For standalone vector database vendors such as Pinecone, Weaviate, Qdrant, and Milvus, this presents an existential threat. Their primary value proposition has been to provide a specialized, high-performance solution for vector storage and search. AWS has now commoditized the basic version of this value proposition, making it available to millions of developers with the flick of a switch in the S3 console. The fight for survival for these vendors now depends on their ability to prove they offer value far beyond what S3 Vectors can provide.
Company-Specific Impact and Response
The introduction of S3 Vectors is forcing specialized vendors to sharpen their focus and differentiate, leading to a variety of strategic responses.
- Pinecone: As a market leader known for performance and ease of use, Pinecone’s strategy is to double down on its strengths: ultra-low latency and a superior developer experience.17 Their messaging emphasizes their purpose-built architecture, which they claim is 25-50x more cost-effective than even AWS’s own OpenSearch for high-throughput workloads.26 They are also rapidly innovating on advanced features like hybrid search using sparse-dense vectors, a capability that provides more precise results by combining semantic and keyword relevance, and one that S3 Vectors does not currently offer in a sophisticated manner.10 Pinecone’s future relies on convincing customers that for mission-critical, real-time applications, the premium for their performance and advanced feature set is justified.
- Weaviate: Weaviate’s open-source nature provides a different line of defense. Its value proposition is centered on flexibility, transparency, and advanced search capabilities, such as its GraphQL API and built-in vectorization modules.27 The company is pivoting towards becoming a platform for specialized AI applications, offering more than just a database.10 For enterprises concerned about AWS vendor lock-in or those who require the ability to customize and self-host their vector search solution, Weaviate remains a compelling option. Many of its users already employ a hybrid architecture, storing source data in S3 and vectors in Weaviate; AWS is now attempting to absorb the latter function.28
- Qdrant, Milvus, and Others: Other players in the market must also find a defensible niche. Qdrant, another open-source option, is strategically focusing on on-premise and multi-cloud deployments, directly targeting the vendor lock-in concerns of large enterprises.10 Milvus, a highly scalable open-source project, competes on its tunable performance and architectural flexibility for massive-scale deployments.29 The survival of these vendors depends on serving the segments of the market that the one-size-fits-all approach of a hyperscaler will inevitably neglect, such as edge computing, specific compliance regimes, or deep customization needs.
The Future of Standalone Vendors: Moving Up the Value Stack
The market is now undergoing a rapid bifurcation into a low-cost “utility” tier, defined by S3 Vectors, and a high-performance “premium” tier. To compete in this new reality, standalone vendors must move up the value stack and differentiate in three key areas:
- Extreme Performance: Guaranteeing consistent, single-digit or low-double-digit millisecond query latencies at massive scale. This is a domain S3 Vectors is not designed to enter, making it the most defensible moat for vendors like Pinecone.10
- Advanced Features: Offering sophisticated capabilities that go far beyond basic ANN search. This includes advanced hybrid filtering, semantic re-ranking, graph-based vector analysis, and integrated data transformation and vectorization pipelines that simplify the end-to-end AI workflow.10
- Deployment Flexibility: Providing a consistent, high-performance solution that can be deployed on any cloud, on-premise, or at the edge. This is a critical requirement for enterprises with multi-cloud strategies or data sovereignty constraints.10
The definition of a “vector database” is blurring. The real value is shifting from the storage component to the application and orchestration layer. This creates an opportunity for standalone vendors to pivot from being simple database providers to becoming “RAG orchestration platforms” or “vector data fabric” providers—tools that help enterprises manage the flow of data across a complex, tiered storage landscape. The companies that successfully make this transition will thrive, while those that continue to compete solely on basic vector storage will face immense pressure from the commoditizing force of AWS.
VI. The Hyperscaler Arena: Competitive Landscape Analysis of AWS, Google Cloud, and Microsoft Azure
Amazon S3 Vectors does not exist in a vacuum. It is AWS’s strategic response in a fierce, three-way competition with Google Cloud Platform (GCP) and Microsoft Azure to dominate the infrastructure layer for AI. Each hyperscaler is aggressively integrating vector search capabilities into its platform, but their distinct strategies reflect their broader market positions and core strengths. Understanding this competitive landscape is crucial for any organization making a long-term platform decision.
Google Cloud Platform (GCP): A Performance-First, AI-Integrated Strategy
Google’s approach to vector search is led by a high-performance, purpose-built service and complemented by deep integration into its data and AI platforms.
- Vertex AI Vector Search: This is GCP’s flagship managed vector search service. It is built upon ScaNN (Scalable Nearest Neighbor), a highly efficient vector search algorithm developed by Google Research, designed to provide low-latency results even at massive scale.15 Vertex AI Vector Search is positioned as an enterprise-grade solution for the most demanding search and recommendation workloads. Its pricing is based on the cost of hosting indexes on virtual machines, with a minimal setup costing under $100 per month, making it accessible but fundamentally an instance-based model.30
- Integrated Database Solutions: Following a strategy similar to its competitors, Google is embedding vector capabilities directly into its core data services. This includes fully managed databases like AlloyDB (PostgreSQL-compatible) and Cloud SQL (for PostgreSQL and MySQL), as well as its planetary-scale data warehouse, BigQuery.31 This allows customers to perform vector search on data where it already lives, reducing data movement and architectural complexity.
- Strategic Philosophy: GCP’s strategy is “top-down” and “AI-first.” By leading with a high-performance engine born from its own research and tightly integrating it with the comprehensive Vertex AI MLOps platform, Google aims to win the most sophisticated and performance-sensitive AI workloads.32
Microsoft Azure: A Strategy of Enterprise Flexibility and Integration
Microsoft has adopted a multi-pronged strategy for vector search, offering the most diverse set of options to meet enterprise customers wherever they are in their architectural journey.
- Azure AI Search: This is Azure’s mature and feature-rich PaaS offering for search, which has been aggressively enhanced with vector capabilities. Its key strength is its first-class support for hybrid search, including sophisticated semantic re-ranking using Reciprocal Rank Fusion (RRF) to merge keyword and vector search results for superior relevance.16 While it requires users to provide their own embeddings, it integrates seamlessly with Azure OpenAI Service to do so.35
- A Broad Portfolio of Vector-Enabled Databases: Azure’s defining characteristic is the breadth of its offerings. Vector search capabilities have been added across its database portfolio, including Azure Cosmos DB (with APIs for NoSQL, MongoDB vCore, and PostgreSQL), Azure Database for PostgreSQL, and Azure SQL Database.22 This gives developers unparalleled choice, allowing them to use the data model and API they are most familiar with.
- Strategic Philosophy: Azure’s strategy is “enterprise-first” and “flexible.” By providing vector support in nearly every database flavor and offering a powerful, dedicated search service, Microsoft caters to the heterogeneous environments of large enterprises. The deep, native integration with Azure OpenAI Service makes it the path of least resistance for building RAG applications on proprietary enterprise data.34
Comparative Analysis: A Strategic Breakdown
The three hyperscalers are converging on the same goal—making vector search a foundational cloud capability—but their approaches reveal different philosophies.
- AWS: Leads with bottom-up cost disruption. S3 Vectors attacks the low end of the market, commoditizing storage and creating a massive funnel into the AWS ecosystem. Performance-sensitive users are then upsold to the more powerful Amazon OpenSearch. The strategy hinges on leveraging the scale of S3 and the popularity of Amazon Bedrock.
- GCP: Leads with top-down performance and AI integration. Vertex AI Search is positioned as the premium, high-performance option, leveraging Google’s deep research expertise. The strategy is to capture the most advanced AI developers and workloads, with vector support in other databases serving as a convenient secondary option.
- Azure: Leads with enterprise flexibility and integration. By offering the widest array of vector-enabled databases and a mature, feature-complete search service, Azure provides a pragmatic on-ramp for its vast base of enterprise customers, minimizing disruption to their existing architectures.
The “best” cloud for vector search is therefore not an absolute but is relative to a customer’s existing technological “center of gravity.” An AWS-native shop will find S3 Vectors compelling, a team building on Vertex AI will prefer GCP’s solutions, and an enterprise deeply embedded in the Microsoft ecosystem will naturally gravitate toward Azure’s offerings. The battle for vector database dominance is not a separate conflict but a new and critical front in the larger cloud platform war.
Table 3: Vector Database Solutions – AWS vs. Google Cloud vs. Microsoft Azure
| Capability | AWS (S3 Vectors / OpenSearch) | Google Cloud (Vertex AI Search / Integrated DBs) | Microsoft Azure (AI Search / Cosmos DB) |
| Primary Service Type | S3 Vectors: Integrated Object Storage | Vertex AI Search: Managed Search Service | Azure AI Search: Managed Search Service |
| OpenSearch: Managed Search Service | AlloyDB/BigQuery: Integrated Databases | Cosmos DB/SQL DB: Integrated Databases | |
| Primary Indexing Algorithm | Inferred HNSW/IVF-PQ (S3 Vectors) | ScaNN (Scalable Nearest Neighbor) | HNSW, Exhaustive KNN |
| HNSW, FAISS (OpenSearch) | |||
| Hybrid Search Support | Basic (metadata filtering) in S3 Vectors | Yes (dense + sparse embeddings) | Yes (first-class feature with re-ranking) |
| Advanced in OpenSearch | |||
| Semantic Re-ranking | No (in S3 Vectors); Available in OpenSearch | Not a native, first-class feature | Yes (Reciprocal Rank Fusion) |
| Max Dimensions | 4,096 (S3 Vectors) | Up to 8,000 in AlloyDB | Up to 16,000 in some services |
| Key Ecosystem Integration | Amazon Bedrock, SageMaker | Vertex AI Platform, BigQuery | Azure OpenAI Service, Microsoft Fabric |
| Pricing Model Philosophy | S3 Vectors: Serverless, pay-per-use (storage + query) | Vertex AI Search: Instance-based (VM hosting cost) | Azure AI Search: Unit-based (tiered capacity) |
| OpenSearch: Instance-based | Integrated DBs: Varies by service | Integrated DBs: Varies by service |
Sources: 15
VII. Strategic Implications and Recommendations for Adoption
The emergence of low-cost, integrated vector storage solutions like Amazon S3 Vectors is not merely an incremental product update; it is a catalyst for a fundamental shift in how organizations should design, build, and budget for AI-powered applications. For technology leaders, navigating this new landscape requires moving beyond a simple choice of database to adopting a more sophisticated, strategic approach to data architecture.
The Tiered Vector Storage Strategy: A New Best Practice
The most significant architectural implication of S3 Vectors is the validation and formalization of a tiered vector storage strategy as a new best practice. A one-size-fits-all approach to vector storage is no longer cost-effective or performant. Instead, organizations should classify their vector data based on latency requirements, query frequency, and business value, and store it in the most appropriate tier.
- Hot Tier (Millisecond Latency): This tier is for data that powers real-time, interactive applications where low latency is critical. Examples include live recommendation engines, interactive RAG chatbots, and real-time fraud detection. This data should reside in a high-performance, in-memory vector database, such as Pinecone, Weaviate, Amazon OpenSearch, or GCP’s Vertex AI Search.10
- Warm Tier (Sub-Second Latency): This tier is for data that is frequently accessed but can tolerate slightly higher latency. This is the sweet spot for Amazon S3 Vectors. Use cases include RAG over large but not real-time document repositories (e.g., the last year of support tickets, a corporate knowledge base), semantic search for internal analytics, and AI agent memory that doesn’t require instant recall.1
- Cold Tier (Archival): This tier is for historical vector data that is queried very infrequently but must be retained for compliance or long-term analysis. S3 Vectors is a highly suitable and cost-effective solution for this tier. In the future, it is conceivable that an even cheaper tier, akin to an “S3 Glacier for Vectors,” could emerge for deep archival.
Adopting this tiered model requires building an intelligent query orchestration layer within the application. This layer is responsible for routing an incoming query to the appropriate data tier(s), fetching the results, and then merging and re-ranking them before passing them to an LLM or user. While this adds complexity, the long-term cost savings and performance optimization benefits are substantial.
Decision Framework: When to Choose S3 Vectors vs. a Dedicated Database
For technology leaders and architects, the choice between a low-cost solution like S3 Vectors and a premium, dedicated vector database can be guided by a clear set of criteria. The following decision matrix translates the analysis of this report into an actionable framework.
Table 4: Decision Matrix – Amazon S3 Vectors vs. Dedicated Vector Database
| Decision Criterion | Choose Amazon S3 Vectors When… | Choose a Dedicated Vector DB When… |
| Query Latency | Sub-second latency (e.g., 200-500ms+) is acceptable. The application is asynchronous or non-interactive. | Millisecond latency (e.g., <100ms) is a strict requirement for the user experience or business logic. |
| Query Volume & Concurrency | Workloads are batch-oriented, have infrequent queries, or have spiky traffic patterns that benefit from serverless scaling. | The application requires very high, sustained query throughput (thousands of QPS) and high concurrency. |
| Cost Sensitivity | Cost reduction is a primary driver. The budget is constrained, or the use case is for development, testing, or a proof-of-concept. | Performance and features are more critical than minimizing cost. The application’s value justifies a premium price. |
| Data Freshness & Update Frequency | The dataset is relatively static, with infrequent updates or deletions. Eventual consistency is acceptable. | The data changes frequently, requiring near-real-time indexing of new data, updates, and deletions. |
| Feature Requirements | Basic similarity search with simple metadata filtering is sufficient. | Advanced features are needed, such as sophisticated hybrid search (sparse-dense), semantic re-ranking, or graph analytics. |
| Operational Simplicity | The team wants to minimize infrastructure management and leverage a fully serverless, managed solution within the AWS ecosystem. | The team has the expertise to manage and tune a database cluster, or the vendor provides a superior, easy-to-use managed service. |
| Multi-Cloud/On-Premise Needs | The organization is committed to the AWS cloud and does not have multi-cloud or on-premise deployment requirements. | A multi-cloud, hybrid, or on-premise deployment strategy is necessary to avoid vendor lock-in or meet data residency rules. |
Recommendations for Enterprise Adopters
Based on this analysis, the following strategic recommendations are proposed for enterprises evaluating their vector data strategy:
- Audit and Classify Your Workloads: Before adopting any new technology, perform a thorough audit of your existing and planned AI applications. Classify each use case based on the criteria in the decision matrix above (latency, query volume, etc.). This will reveal where a low-cost solution like S3 Vectors is appropriate and where a high-performance database remains necessary.
- Embrace S3 Vectors for Development and Prototyping: The serverless nature and negligible starting cost of S3 Vectors make it the ideal platform for experimentation. Encourage development teams to use it for building proofs-of-concept and testing new RAG applications. This lowers the barrier to innovation and provides hands-on experience with the service’s capabilities and limitations.10
- Target Latency-Tolerant RAG as the Primary Use Case: For the common and high-value use case of building a RAG system over a large, relatively static corpus of documents, the combination of Amazon S3 Vectors and Amazon Bedrock Knowledge Bases is a purpose-built, highly cost-effective, and scalable solution that should be strongly considered.1
- Invest in a Tiered Architecture for Scalability: For complex, enterprise-wide AI systems, design for tiering from the outset. Architect your applications with a flexible data access layer that can abstract the underlying storage, allowing you to route queries to the optimal data store—be it S3 Vectors, OpenSearch, or a third-party database—based on the query’s context or the data’s age.
- Benchmark Before Committing: Do not rely solely on marketing claims. Conduct a proof-of-concept with your own data and representative query patterns to validate the performance and cost savings of S3 Vectors for your specific workload. This data-driven approach will ensure your final architectural decision is sound.
Outlook: The Future of Vector Search as a Foundational Cloud Capability
The integration of vector search into Amazon S3 is a clear indicator that this technology is transitioning from a niche, specialized tool to a foundational capability of modern data platforms. It is rapidly becoming as essential as keyword search, SQL querying, or JSON support. In the coming years, we can expect to see continued commoditization at the storage layer, deeper integration with other cloud services, and an innovation race that shifts from raw search performance to the intelligence of the application layer, the ease of the developer experience, and the sophistication of the tools that manage the end-to-end AI data lifecycle. The era of the standalone vector database is not over, but its role has been irrevocably changed. The future belongs to those who can master the complexity of a multi-tiered, hybrid vector data landscape.
Works cited
- Building cost-effective RAG applications with Amazon Bedrock …, accessed July 25, 2025, https://aws.amazon.com/blogs/machine-learning/building-cost-effective-rag-applications-with-amazon-bedrock-knowledge-bases-and-amazon-s3-vectors/
- Announcing Amazon S3 Vectors (Preview)—First cloud object storage with native support for storing and querying vectors – The AWS News Feed, accessed July 25, 2025, https://aws-news.com/article/2025-07-15-announcing-amazon-s3-vectors-previewfirst-cloud-object-storage-with-native-support-for-storing-and-querying-vectors
- Introducing Amazon S3 Vectors: First cloud storage with native …, accessed July 25, 2025, https://aws.amazon.com/blogs/aws/introducing-amazon-s3-vectors-first-cloud-storage-with-native-vector-support-at-scale/
- AWS adds vector buckets to S3 to cut RAG storage costs – Blocks and Files, accessed July 25, 2025, https://blocksandfiles.com/2025/07/17/aws-vector-buckets-s3/
- Using Amazon S3 Vectors (preview) to semantically search using a media lake on AWS, accessed July 25, 2025, https://aws.amazon.com/blogs/media/using-amazon-s3-vectors-preview-to-semantically-search-using-a-media-lake-on-aws/
- Hands-On with Amazon S3 Vectors (Preview) + Bedrock Knowledge Bases: A Serverless RAG Demo : r/aws – Reddit, accessed July 25, 2025, https://www.reddit.com/r/aws/comments/1m5acx8/handson_with_amazon_s3_vectors_preview_bedrock/
- AWS S3 Vectors Explained: The Ultimate Guide to 90% Cheaper GenAI & RAG Storage, accessed July 25, 2025, https://medium.com/@ismailkovvuru/aws-s3-vectors-explained-the-ultimate-guide-to-90-cheaper-genai-rag-storage-a6f162bf1aa2
- Amazon S3 Vectors Explained: Regions & Setup – DEV Community, accessed July 25, 2025, https://dev.to/aws-builders/s3-vectors-explained-regions-setup-2ik2
- Amazon S3 Vectors: Revolutionizing AI Data Storage with Use Cases | AWS re:Post, accessed July 25, 2025, https://repost.aws/articles/ARY9EKiGFISfisAyvigDX3lQ/amazon-s3-vectors-revolutionizing-ai-data-storage-with-use-cases
- AWS S3 Vectors vs Traditional Vector Databases: The Enterprise …, accessed July 25, 2025, https://ragaboutit.com/aws-s3-vectors-vs-traditional-vector-databases-the-enterprise-cost-analysis-that-changes-everything/
- Amazon S3 Pricing – Cloud Object Storage – AWS, accessed July 25, 2025, https://aws.amazon.com/s3/pricing/
- AWS S3 gets vector buckets with new algorithms for reasonable performance at lower cost, VP tells us – devclass, accessed July 25, 2025, https://devclass.com/2025/07/17/aws-s3-gets-vector-buckets-with-new-algorithms-for-reasonable-performance-at-lower-cost-vp-tells-us/
- Announcing Amazon S3 Vectors (Preview)—First cloud object storage with native support for storing and querying vectors : r/aws – Reddit, accessed July 25, 2025, https://www.reddit.com/r/aws/comments/1m12r14/announcing_amazon_s3_vectors_previewfirst_cloud/
- What Is A Vector Database? – IBM, accessed July 25, 2025, https://www.ibm.com/think/topics/vector-database
- What is a vector database? | Google Cloud, accessed July 25, 2025, https://cloud.google.com/discover/what-is-a-vector-database
- Understanding Vector Databases | Microsoft Learn, accessed July 25, 2025, https://learn.microsoft.com/en-us/data-engineering/playbook/solutions/vector-database/
- Pinecone vs Amazon OpenSearch Serverless: Which Vector Database Powers Your AI Applications Best in 2025? – Empathy First Media, accessed July 25, 2025, https://empathyfirstmedia.com/pinecone-vs-amazon-opensearch-serverless/
- Vector Database: 13 Use Cases—from Traditional to Next-Gen – Instaclustr, accessed July 25, 2025, https://www.instaclustr.com/education/vector-database/vector-database-13-use-cases-from-traditional-to-next-gen/
- What are vector databases and should you be using one? – Contentful, accessed July 25, 2025, https://www.contentful.com/blog/what-are-vector-databases/
- What Is A Vector Database? Top 12 Use Cases – lakeFS, accessed July 25, 2025, https://lakefs.io/blog/what-is-vector-databases/
- Top 10 Vector Database Use Cases in 2025 – Research AIMultiple, accessed July 25, 2025, https://research.aimultiple.com/vector-database-use-cases/
- Integrated vector database – Azure Cosmos DB | Microsoft Learn, accessed July 25, 2025, https://learn.microsoft.com/en-us/azure/cosmos-db/vector-database
- Vector Database Market Size, Share & Trends | Forecast, 2028 – MarketsandMarkets, accessed July 25, 2025, https://www.marketsandmarkets.com/Market-Reports/vector-database-market-112683895.html
- “Amazon S3 Vectors Just Killed the Vector Database Market” | by …, accessed July 25, 2025, https://medium.com/@ajinkyachatufale/amazon-s3-vectors-just-killed-the-vector-database-market-cec4ce2347ee
- Vector Databases Are Officially Dead? Here’s What AWS Just Did | Front Page – YouTube, accessed July 25, 2025, https://www.youtube.com/watch?v=qglKh119DNE
- Pinecone vs OpenSearch, accessed July 25, 2025, https://www.pinecone.io/solutions/pinecone-vs-opensearch/
- Vector database : pgvector vs milvus vs weaviate. : r/LocalLLaMA – Reddit, accessed July 25, 2025, https://www.reddit.com/r/LocalLLaMA/comments/1e63m16/vector_database_pgvector_vs_milvus_vs_weaviate/
- Optimizing Weaviate for Image Embedding Search without Storing Images, accessed July 25, 2025, https://forum.weaviate.io/t/optimizing-weaviate-for-image-embedding-search-without-storing-images/498
- How do vector databases like Milvus or Weaviate handle storage of vectors and indexes under the hood (e.g., do they use memory-mapped files, proprietary storage engines, etc.)?, accessed July 25, 2025, https://milvus.io/ai-quick-reference/how-do-vector-databases-like-milvus-or-weaviate-handle-storage-of-vectors-and-indexes-under-the-hood-eg-do-they-use-memorymapped-files-proprietary-storage-engines-etc
- Vector Search | Vertex AI | Google Cloud, accessed July 25, 2025, https://cloud.google.com/vertex-ai/docs/vector-search/overview
- Vector Search and Embeddings across GCP products | Google Cloud – Medium, accessed July 25, 2025, https://medium.com/google-cloud/making-sense-of-vector-search-and-embeddings-across-gcp-products-46cedad68934
- Vector Search and Embeddings | Google Cloud Skills Boost, accessed July 25, 2025, https://www.cloudskillsboost.google/course_templates/939
- Vector store database – Azure AI Search | Microsoft Learn, accessed July 25, 2025, https://learn.microsoft.com/en-us/azure/search/vector-store
- Choose an Azure service for vector search – Azure Architecture …, accessed July 25, 2025, https://learn.microsoft.com/en-us/azure/architecture/guide/technology-choices/vector-search
- Choosing the right Azure Vector Database | by Michael John Peña – Medium, accessed July 25, 2025, https://medium.com/@mjtpena/choosing-the-right-azure-vector-database-d62a64f30e68
- Vector databases in Azure: 6 service options and how to get started – Instaclustr, accessed July 25, 2025, https://www.instaclustr.com/education/vector-database/vector-databases-in-azure-6-service-options-and-how-to-get-started/